CCBot is the web crawler of Common Crawl, a non-profit that builds a free, open archive of web pages. Anyone can download that archive, and AI developers have used it as training data, so blocking CCBot is a single opt-out with a wide reach, but it doesn't remove pages already archived.
CCBot is the web crawler of Common Crawl, a non-profit that builds a free, open archive of web pages. Anyone can download that archive, and AI developers have used it as training data, so blocking CCBot is one opt-out with a wide reach.
What does it collect, and who uses the archive?
It collects the public HTML of web pages for an archive that anyone may use. Common Crawl says its corpus “contains petabytes of data, regularly collected since 2008”, and describes the goal as a repository that is “universally accessible and analyzable by anyone”.
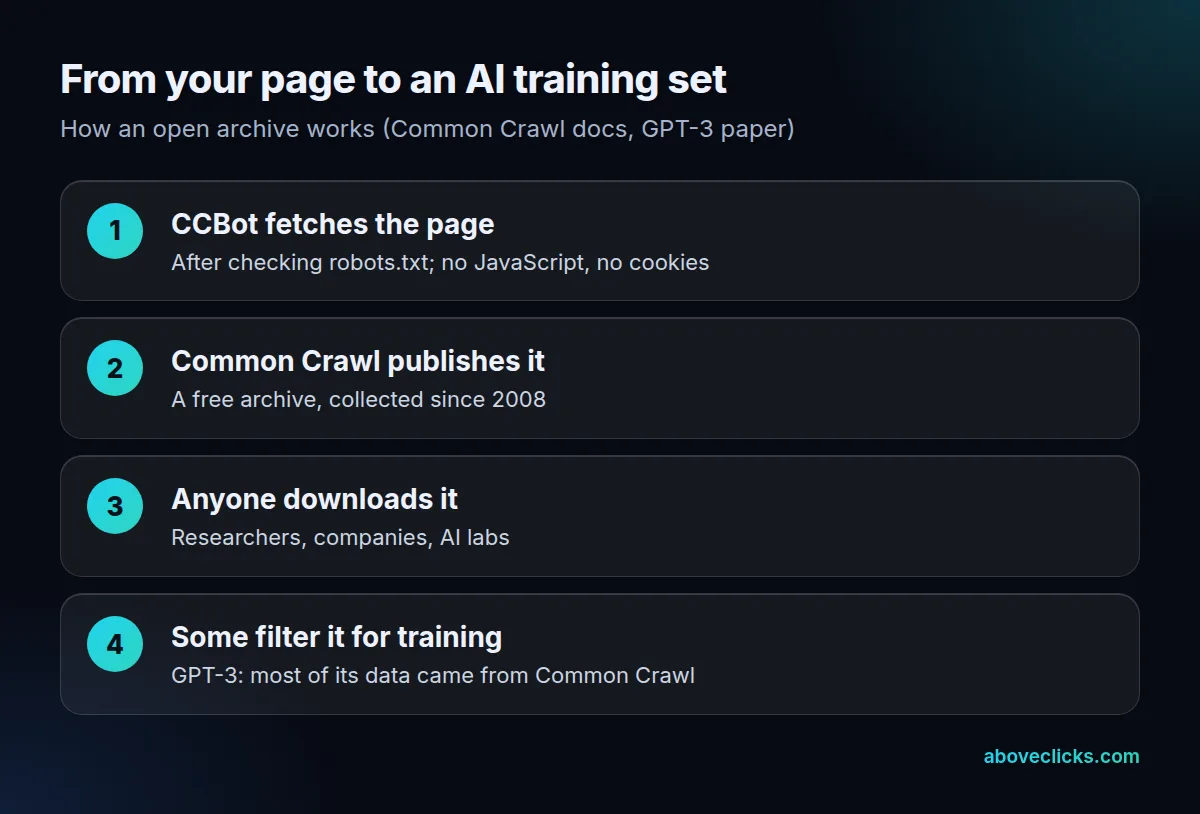
AI developers are among those users. OpenAI’s 2020 GPT-3 paper says “the majority of our data is derived from raw Common Crawl with only quality-based filtering” (Brown et al., arXiv). Its training table lists filtered Common Crawl at 410 billion tokens and a 60% weight in the training mix, the largest single source. That’s one documented example, not a list of every model trained on the archive.
For a store, the point is reach: a page in the archive can end up in datasets you’ll never hear about, built by teams that never crawled your site.
How do you block CCBot?
Add a robots.txt group for its token. The FAQ gives the exclusion user agent as the bare name, so User-agent: CCBot followed by Disallow: / stops future crawls of the whole site. The crawler checks robots.txt before it fetches anything else.

If load is the issue rather than reuse, it obeys Crawl-delay. The FAQ’s example, Crawl-delay: 2, limits the crawler to one request every 2 seconds, which keeps a small hosting plan responsive while your pages still enter the archive. Put the group in the robots.txt of each host you want covered, including any shop or blog subdomain.
Does blocking it remove you from AI models?
No. A Disallow rule stops future crawls; it doesn’t reach into archives already published or datasets already built from them. Treat it as a decision about future pages, and remember that other training crawlers, such as GPTBot and ClaudeBot, need their own groups.
It also doesn’t affect search. Google Search crawls with Googlebot and ChatGPT search with OAI-SearchBot, and each robots.txt group applies only to the bot it names. In our check of 30 jewelry, fashion and beauty stores on 17 October 2026, none of the 25 readable robots.txt files named this crawler, against 2 that named GPTBot.

How do you recognise CCBot in your logs?
Look for the user agent string that starts with CCBot/2.0 and check the IP. Common Crawl says CCBot runs on dedicated IP ranges with reverse DNS; its JSON list held 5 ranges (4 IPv4, 1 IPv6) when we downloaded it on 17 October 2026.
Two habits matter for stores: it follows up to 4 consecutive redirects, and JavaScript isn’t executed, so product text injected by scripts never reaches the archive. Server-rendered HTML is what it keeps, the same thing our technical SEO work checks for search crawlers. For AI visibility more broadly, see our generative engine optimization service and the AI search optimization hub.