Applebot-Extended is a robots.txt token that lets publishers opt out of their content being used to train Apple's foundation models. It doesn't crawl pages, and Apple says it isn't considered in Search ranking. Apple's AI-written world-knowledge answers have a separate control: the nosnippet meta tag.
Applebot-Extended is a robots.txt token that lets publishers opt out of their content being used to train Apple’s foundation models. Applebot Extended doesn’t crawl anything itself, and Apple says it isn’t considered in ranking for Search.
What does Applebot Extended control?
How Apple may use what its crawler has already fetched. Apple’s support article says the token lets publishers opt out of training Apple’s “general purpose foundation models powering generative AI features”, covering 3 areas: Apple Intelligence, Services and Developer Tools. Those Apple foundation models run features across the company’s devices, so this is the one switch for Apple’s training use.
It’s one of Apple’s 2 robots.txt tokens: the crawler’s own token controls fetching, and the extended one only governs data use. That split is why none of the 25 store robots.txt files we read on 17 October 2026 needed to touch it to keep Spotlight and Siri working.
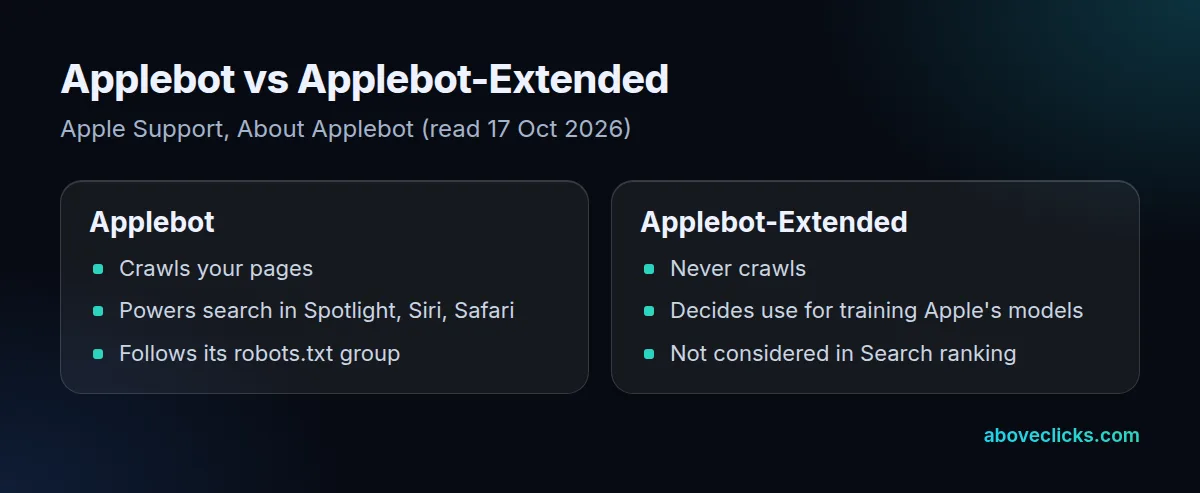
Apple is explicit that “Applebot-Extended does not crawl webpages”. It’s “only used to determine how to use the data crawled by the Applebot user agent”, so you’ll never see it in server logs; the visits you see come from the crawler itself.
Does disallowing it remove you from Siri and Spotlight?
No. Apple says “Webpages that disallow Applebot-Extended can still be included in search results”, and that its rules “are not considered in ranking for Search”.
The crawler is what powers search in Spotlight, Siri and Safari. Blocking it, not the extended token, is what would take a store out of those 3 places, which is rarely what anyone wants. Apple says genuine crawler traffic is identified by reverse DNS in the applebot.apple.com domain, so check the host name of any IP that claims to be Apple’s.
None of the 25 readable store robots.txt files in our 17 October 2026 check blocked Apple’s crawler, so on the stores we saw, Siri and Spotlight access was never in question.
How do you opt out of Apple’s AI answers too?
Use the nosnippet meta tag on the pages concerned. Apple says Applebot data may add context when AI models generate answers to “broad world knowledge questions in Siri and Search”, and that publishers opt out of those answers “by applying the nosnippet meta tag”.

So Apple has 2 separate switches for AI use, and Applebot Extended is only one of them: the token for training and nosnippet for AI-written answers. Apple adds that pages marked isAccessibleForFree: false stay searchable but aren’t used as that extra context.
How do you add Applebot Extended to robots.txt?
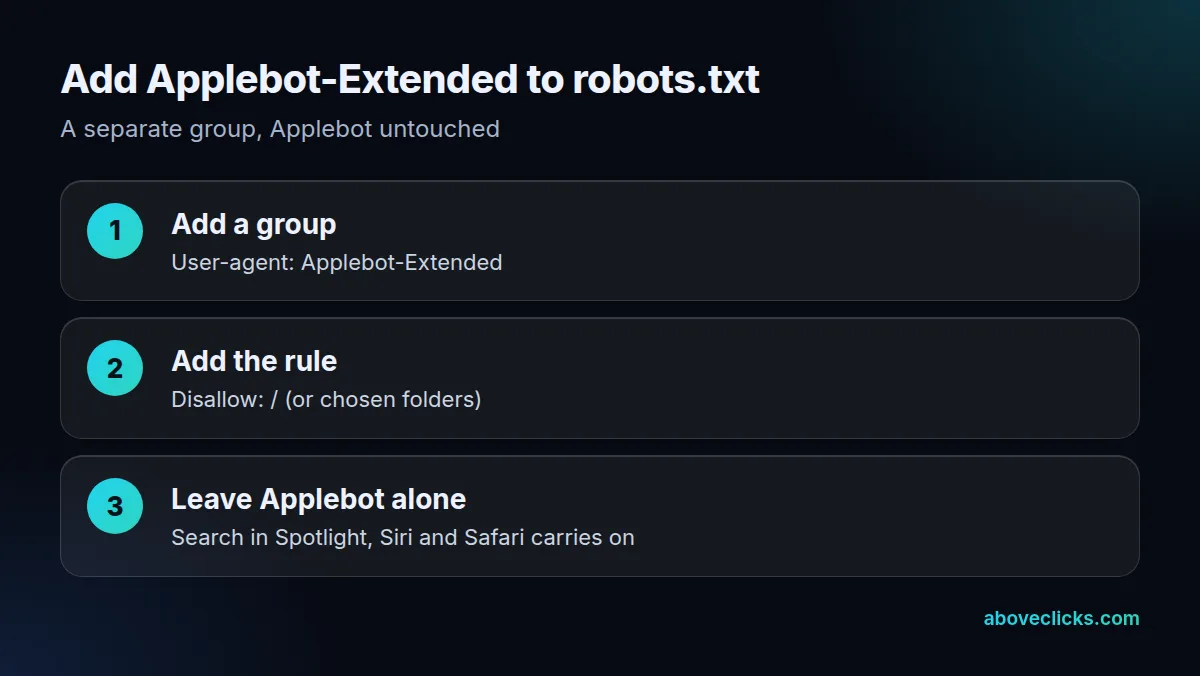
Give it its own group: User-agent: Applebot-Extended with Disallow: /, and leave your Applebot group as it is.
User agent names are matched case-insensitively under RFC 9309 and Google’s spec. In our check of 30 jewelry, fashion and beauty stores on 17 October 2026, none of the 25 readable robots.txt files named either token, so all 25 leave both to their general rules, which allow training use. For crawl rules across every engine, see our technical SEO service; for AI visibility, our generative engine optimization work and the AI search optimization hub.